Ask around at a 15,000-person developer conference what people learned about AI, and you’ll get opinions about tools, tokens, and whichever model just shipped that week, half of it stale by the time you’re back at your desk.
Ask the right people, though, and you’ll get the same answer twice, from directions you didn’t expect.
That’s roughly what happened at WeAreDevelopers World Congress 2026 in Berlin. Levi niners followed sessions across AI-driven engineering, quality assurance, and mobile development, and came home with what is, underneath the different vocabularies, one shared realization: writing code was never the hard part. Verifying it, and standing behind the solution it’s part of, was hard part. Now that AI writes most of the code, that’s the whole job.
Mirko Tomić’s award at CODE100 live competition was undoubtedly one of the highlights of our week in Berlin. But conferences are about more than what happens on stage. Between sessions, meetups, and countless conversations, our colleagues gathered insights, challenged assumptions, and came home with fresh perspectives. Here’s what stood out to them.

Code got cheap. Verification didn't.
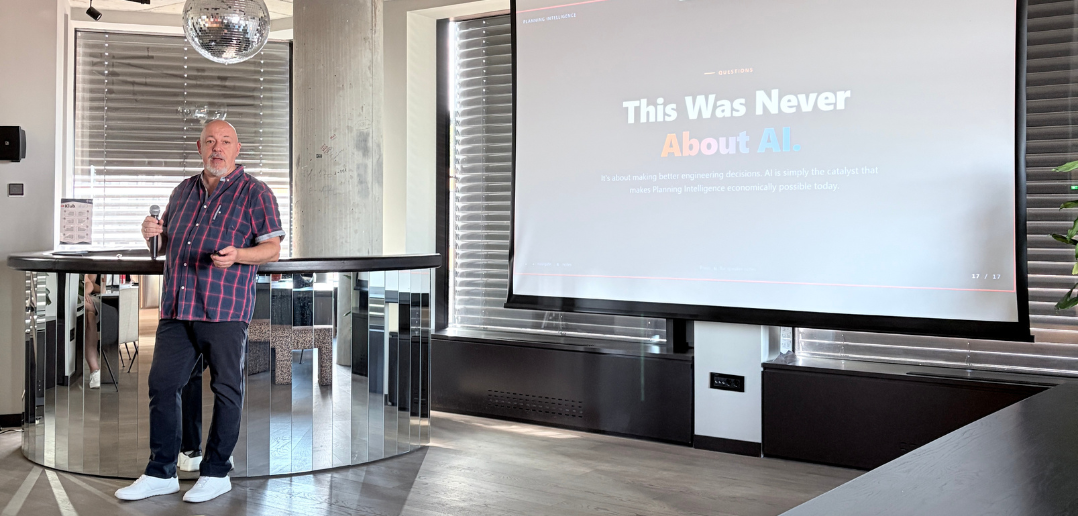
At the IBM session “Code Is Cheap. Software Isn’t,” AI Developer Strategist Markus Eisele made the point plainly: generating code has become fast and easy, while understanding, validating, and trusting that code is now the actual bottleneck.
His line stuck with levi niner Katarina Stanisavljević enough to write it down: “If you cannot verify it, do not delegate it.”
Katarina’s own takeaway from the session went a step further: “AI is not replacing engineering, it is making engineering visible again.” The value isn’t disappearing, it’s moving, from producing code to understanding problems, defining intent, and owning the quality of the whole solution. The same idea surfaced again in the QA sessions, where the recurring theme was that AI output has to be treated as untrusted input by default, not because AI is unreliable, but because “a model produced it” was never a safety guarantee to begin with.
Sessions that had the biggest impact on me was “Designing for Flow: How Atlassian Williams F1 Team is Building an AI-led System of Work” by Andrew Boyagi, Customer CTO at Atlassian. As a big Formula 1 fan, this session immediately caught Katerina’s attention, but what made it truly interesting was seeing how AI can support engineering teams in such a demanding and competitive environment. It was fascinating to see how Williams F1 approaches collaboration, workflows, and decision-making with the help of technology.
„AI is helping teams focus on what creates the most value. The key ideas that stayed with me were the importance of focusing on high-priority issues, improving collaboration between teams, and preventing duplicate effort. It was a great example of how AI can help complex engineering organizations become more efficient while keeping human expertise and decision-making at the center.” Katarina shares.

Beyond the talks, Katarina explored hands-on workshops focused on multi-agent systems, including Google’s Agent Development Kit (ADK) and Agent-to-Agent (A2A) protocol. She also came across tools such as MCPc, designed to improve agent integrations and workflows, and AIQSpecFlow, which brings AI into requirements management and testing. Together, they illustrated how AI is expanding beyond code generation to support the entire software delivery lifecycle, from specification and planning to testing and quality assurance.
Reflecting on the experience, Katarina said: “What I found especially valuable was moving beyond theory and seeing how these concepts can be applied when building real-world AI solutions.”
The test becomes the control surface
Our colleague Svetozar Toza Pavlović came back from a cluster of testing sessions with a sharper version of the same idea. For him, the most valuable takeaways came from sessions that challenged traditional approaches to quality assurance in AI-driven software development.
Talks by Maish Saidel-Keesing (AWS), Ondřej Gróf (Canva) and Sebastian Messingfeld (Eurowings Digital) explored how testing, evaluation, and quality processes need to evolve in a world where AI agents increasingly participate in software delivery. Together, they painted a picture of quality as a shared responsibility, continuous evaluation as a necessity, and testing as a critical control mechanism rather than a final checkpoint.
One message resonated particularly strongly: “When an agent writes the code, the test becomes the control surface. It steers and constrains the agent rather than simply verifying it, so it is worth investing more in test quality, because the agent scales both good and bad.”
The sessions also highlighted the importance of building robust evaluation systems before selecting models and of pushing verification to the most deterministic layer possible, reserving human attention and LLM-based judgment for truly complex cases. As AI agents become part of everyday engineering workflows, these practices are increasingly becoming the foundation for reliable and scalable software delivery.
Another insight that stayed with Toza came from the realization that AI changes not only how software is built, but also what quality means. “Build the eval before you pick the model, and treat it as durable infrastructure. It outlives any single model and makes switching a routine, data-driven operation.” In an ecosystem where models evolve rapidly, the ability to measure, compare, and continuously evaluate outcomes may prove more valuable than any individual technology choice.
The conference reinforced a shift already underway across the industry. As AI takes on more implementation work, greater importance is placed on clearly defining system behavior, expected outcomes, and evaluation criteria. At the same time, quality is increasingly emerging as a shared capability embedded across teams, supported by continuous evaluation rather than one-time sign-off processes.
As Toza explains:
“The QA role is shifting from verification toward specification and orchestration. Two things point the same way. First, as AI writes more of the code, the value moves upstream, into stating clearly what the system is supposed to do rather than checking line by line what it did. Second, quality is increasingly treated as a shared, self-service capability across the team rather than something owned by a separate QA function. The related shift is that AI systems need to be evaluated continuously rather than signed off once, because they change even when the code doesn’t.”

As organizations move from experimenting with AI to building production-ready systems around it, he sees this intersection of quality engineering, security, and AI evaluation as one of the most important areas for professional growth.
Owning the solution, not just the spec
Our colleague Kristijan Iker sat through sessions on Swift moving into serverless and AI running natively on-device, different tools entirely, and landed on the same conclusion as the others, put in his own words: “If specification is up to date, then nothing else matters.”
That’s not a claim that specification is the finish line. It’s the starting condition for actually owning the solution. If the whole team, mobile, backend, QA, and the people who understand the business problem, can align on a shared, precise definition of what the system should do, AI can handle a good part of the implementation on essentially any platform, in any language.
But someone still has to stand behind the result: decide it’s right, decide it’s done, and be accountable for it working in production. That’s not a task you delegate to a model.
As Kristian puts it:
“Whole team, different background and minds can contribute from their field of expertise, should work on project specification together, once everything is defined and polished, AI can easily handle implementation on any platform, do any test writhing, cover all automation, we just make sure end result is what we expect it to be, do final test and move on to next feature.”
The idea surfaced repeatedly throughout the event: as AI becomes more capable of generating code and automating delivery tasks, the real differentiator shifts upstream. The challenge is no longer only how to build a solution, but how clearly a team can define it, align on it, and take responsibility for the outcome once it reaches production.
Three things worth taking into any engineering roadmap
Invest in the specification, but don’t stop there. Spec-driven testing, deriving tests from requirements with traceability back to them, was one of the most transferable ideas across every session. It’s necessary. It’s not sufficient on its own: someone still owns the judgment call on top of it.
Treat AI output as untrusted input, structurally. That means guardrails as a layered, shared service rather than something each team bolts on, and routing model calls through a single layer where cost, quality, and provider can all be watched and adjusted in one place.
Build the eval, not the hype. Several speakers were explicit that AI tooling on its own delivers limited returns, the gains come from rethinking how the work around it is organized. Chasing every new model demo is a distraction from the infrastructure (evals, context engineering, clear specs) that actually compounds.
None of this is really about Berlin. It’s about what happens when people across very different disciplines all bump into the same wall at the same time: AI can write the code, but someone still has to own the solution.
If your team is generating code faster than it can verify it, struggling to define the right requirements, or trying to understand where AI fits into the delivery lifecycle, that’s a conversation we’re already having with clients. Get in touch with Levi9 and let’s compare notes.
In this article: